
OpenAI vs Mathematicians, Vibe-Coded Adobe, and AI’s Wolf Emails
YouTube will ask you to confirm your subscription.
About this episode
OpenAI’s claim to 700 maths solutions comes with a big catch: someone still has to check them. Justin thinks mathematicians need to adapt and put AI to work. Frank worries that answers without understanding leave us with a dangerous gap. And while Justin is happy to patch mistakes in maths, he’s freaking Frank out with the idea of biology labs using AI solutions that still contain errors.
Plus: A vibe-coded Adobe clone raises questions about who you trust to build and support your software, AI models tackle cells and plant DNA, and European labs give Justin something to cheer about. An AI agent emails thousands of people, including a wolf researcher, while trying to fix its own code.
JOIN THE ARGUMENT
Would you trust an AI answer you couldn’t check yourself?
Sources
- Isomorphic Labs joins the Virtual Biology Initiative to build foundational data for AI models to predict and treat disease
- Two Room-Temperature Antiferromagnetic Semiconductor Candidates
- Living Models pairs Gemma 4 with BOTANIC-1 to help decode plant DNA
- BOTANIC-1: a series of long-context plant genomic foundation models in the agentic era
- FLUX 3 - Real World Models: Towards Multimodal Flow Models as the Backbone of Visual Intelligence.
- Introducing Mistral Large 4
- Aleph Alpha releases Kolibri
- The First Room-Temperature Ambient-Pressure Superconductor
- Z.ai’s GLM models, including GLM Flash
- Sharing AI progress in mathematics
- AHM Statement on OpenAI’s October 6 Release of Mathematical Documents
- Navier-Stokes lost in translation: Why Lean verification of AI autoformalisation does not guarantee correct natural language proofs
- First AI came and scooped up your art. Now it’s scooped up Adobe.
- Exclusive: An AI agent emailed hundreds of researchers for help. It told us why
Key insights
Does solving maths faster leave us with more work?
OpenAI released hundreds of claimed maths solutions, leaving mathematicians with a huge checking task. Justin sees a reason to improve how that work gets done. Frank worries we’re losing the understanding built through solving problems ourselves. Producing answers quickly still leaves the hard work of checking and understanding them.
Would you trust free software without someone to call?
A vibe-coded Adobe alternative sounds tempting until you ask who fixes it when something breaks. Frank hasn’t been willing to install it. Justin sees a possible business opportunity: companies that support AI-built software. Building the product may get easier, while earning enough trust for people to use it stays hard.
What happens when AI curiosity eats into scientists’ working hours?
An AI agent emailed a wolf researcher to ask whether his methods could help find software bugs. It had contacted thousands of people. That’s fascinating, but the time is unevenly shared: an agent can send questions at scale, while researchers have limited hours to answer. Who benefits from that exchange?
TranscriptThis transcript was generated with AI and may contain errors.Read full transcript
Justin: Hello. Good morning, good afternoon, good evening, and welcome to the AI Argument. We're here this week to discuss what is becoming fast, the the singularity update. Again, I mean, you're here joined by me, the always right, always optimistic Justin Collery, and the ever cautious but the ever more regularly maybe right but maybe not so right, Frank Prendergast, I think at least.
Hi, Frank.
Frank: How's it going, Justin?
Justin: Pretty good. And how's your week going?
Frank: Not too bad, not too bad. I am a little bit sleep-deprived right now, so I'll probably make even less sense than I usually do on this show. So I expect not to be able to keep up this week with the Singularity Update. My brain might just melt.
Justin: Brilliant. I'll take advantage of that to try and win a couple of extra arguments this week.
What's in this week's singularity update?
Justin: This week in the Singularity Update, and if you didn't notice, w- I mean, it's just getting crazier and crazier and crazier. So let me just bring you through a quick roundup. Isomorphic and Google DeepMind and Meta are joining partners in this, what they're calling the Virtual Biology Initiative.
It's a universal predictive model to predict what happens in the cell, right? It's gonna help.
Frank: I was right. My brain's melting already.
Justin: In 19-- in three days, 90 Plus Opus 5.5 agents helped uncover two room temperature potentially semiconductor candidates. I'm old enough to remember the big furore over LK-99, which happened about two years ago, and one of these materials was actually already discovered in 1999, and people just didn't realise it might have been a semiconductor.
But now AI says maybe it is, which is kind of cool. And then AI research lab Living Models is working with Google Gemma 4 for BOTANIC-1, a specialised AI trained on plant DNA. Now, this one is an interesting one, right? So what they want to do is they want to build a predictive model for plant DNA so that you can mutate the DNA to make the plants, you know, more resistant to climate change or more able to grow in areas with less than perfect soil and all that sort of.
This is a good thing, right? It's gonna help to feed more people. But given the furore in Europe over GM crops in the past, I can't see the Europeans being too happy about AI mutated crops.
Frank: Was it The Day of the Triffids that had those huge walking plants that could eat humans?
Justin: Come back to that.
Can Mistral help Europe defend itself?
Justin: Speaking of Europe though, right, this has been an incredible week for Europe. We have had not one but three state-of-the-art, in their own areas, models released from European labs, and I'm always sort of saying, "Europe needs to do better," blah, blah, blah, blah. Go Europe, right?
So we've had FLUX 3, which is from a company, I believe, in Sw- Sweden, and they've released a model which is the strongest world model in the world. That is the thing which Yann LeCun says we need in order to get to AGI. So a world model is understanding what happens when a cup drops off a table, for instance.
It doesn't just predict the next word, it actually understands why the cup breaks.
Frank: Interesting. Flux, aren't they the-- Like, they're the company who previously had-- They have a really good image generator. So it's interesting that maybe presumably the world model was maybe always their end goal, and the image generator was something that they were doing along the way.
Justin: Yep, brilliant. Mistral our French, our favourite French AI company. This one is interesting, right? So they have re-released Le Chonk, and I'm a little bit disappointed they didn't call it Le Fat Cat, 'cause that's what I thought they were gonna release their next model. But this one is state-of-the-art in open source models when they compare themselves against the European and other US models.
It's not state-of-the-art relative to the Chinese models. The things that it's really good at, however, are cyber defence and critical workloads, and I don't think that's an accident, right? So I do think that cyber defence using AI is gonna be a crucial thing in the future, and the French are very good at taking on big engineering projects that are good for their sovereignty.
So they are the only country in Europe that has loads of nuclear power stations, so they're not dependent on foreign oil. They are the only country in the European Union, that I'm aware of, that has nuclear weapons because they wanted to ensure that they were protected. I think there might be something similar going on here, where now they're creating AI models and they're creating them for cyber defence.
It's kind of the same.
Sort of a thing.
Frank: Yeah, I mean, it makes perfect sense because if you remember even, say, the Hugging Face incident when they were being hacked by an OpenAI model, they didn't know who was attacking them. They just knew that they were being attacked. They couldn't defend using the-- excuse me, they couldn't defend using Claude or ChatGPT because Claude and ChatGPT interpreted it as they were actually trying to hack someone themselves.
They had to go to an open source model. I think they used Chinese models, but as we know, a lot of companies are not comfortable using Chinese models, and the same would go for nations, you know. So in the EU, if we wanna defend ourselves against cyber attacks, it would make so much more sense to be using an open source French model that is installed on your own infrastructure.
Justin: Absolutely. And, but model number three to come out of Europe this week is, it's called Kolibri. It's from a company called Aleph Alpha. This one is exciting. This one comes out of Germany, so it's gonna be really good at filling in forms and following regulations and stuff like that. That's a joke. That's a joke. Joking about that. It comes, comes out of Germany, and why this one is so exciting is they made it in two months, two months with limited resources, and they've released a model which is about the GLM Flash type level. So it's not a, like a ridiculously strong model. What's impressive is the speed of progress, and I think that points to, you know, potentially a bright future that if you have-- I mean, Europe has the researchers, we have the skills we now need power stations and we need data centres, and we need loads of them.
We should be building nuclear power stations to beat the band. In the future, your wealth is going to be dictated by how much power you have, and, you know, we have the brains, we have the ability, we just need the power.
Frank: And underlying all of that, we need the money.
Justin: Well, y- well, I was reading an article this week, interestingly, and it was about the transfers of money from European pension funds to American data centres, and apparently there's a lot. And so the issue isn't that Europe doesn't have the money, the issue is that all the return on that money goes to America.
So if we had opportunities in Europe to spend that money, maybe, you know, investors would be more likely to spend the money in Europe. So, cool.
Has OpenAI solved maths or stirred trouble?
Justin: This of all, all of these things, however, is not the biggest news of the week. The biggest news of the week by far is that OpenAI released the re- the solution to 700 maths problems, and the maths world is going mad.
Now, let me remind you, right, 'cause I did-- this is the Justin is Right episode. In June, how many maths problems had we solved? I think it was three, and we had done some gold medal stuff. In August, that number had risen to 10, and here we are in October, and we are now at 700 maths problems. Now, I'm not great at maths, and I'm not great at graphs, but that seems to me like a graph that goes like that, where the number of problems being solved every month is growing and growing.
And the maths, the maths fraternity are really, really upset. What do you think?
Frank: Yeah. I mean, it's interesting, isn't it? 'Cause I mean, it, you know, it, as you say, it sounds like a good thing. It sounds like, hey, AI is actually doing something practical and, you know, presumably if we've been trying to solve these maths problems for as long as we have been, there's a reason for that. These solutions should be useful.
You would think that this would be a net positive thing for humanity.
Justin: Not an...
Frank: Do not seem to believe so.
Justin: Well, no, the purpose of these maths problems, Frank, was not for the good of humanity. It was to keep maths professors in jobs in tenured universities for long periods of time, it would.
Frank: Oh. Oh, very, very cynical.
Does solving maths cost us understanding?
Justin: So there's a, go on, there was a letter released. I mean, you've done a bit of research into this. There was a letter I saw yesterday. I mean, it was just incredible. I mean, the letter I think started with, you know, OpenAI, the company which is currently under, you know, investigation for breaches of copyright, whatever, and it just sort of went into a diatribe about how terrible OpenAI was.
And then it was like, you know, "We're mathematicians, we have established processes for spending years solving these problems. You cannot just come out and solve them all at once. This isn't playing ball."
Frank: Yeah, I think, yeah, one of the, one of the first lines that jumped out at me was, "Mathematicians did not ask for this." Excuse me. And I think what's-- You know, it is interesting, there's a little bit of history preceding this letter because I think it was after the Navier-Stokes problem was solved. I find it so weird that I even know the name of the Navier-Stokes problem now. So the OpenAI solved the Navier-Stokes problem, and I think it was after that there was like 25 human Fields Medal winners signed a letter outlining why it might not be a great thing that AI is solving these problems. And I, you know, I think that the core thing is, -- and, and they acknowledge that this isn't specific to maths.
All of humanity, every industry, every niche is facing this problem where the solution to a problem isn't necessarily the goal for humanity. It's the journey to that solution and the insight and the understanding and the experts that that develops develops along the way. And if we lose that, then, you know, humanity is no longer contributing and creating new skills, new understandings, new questions that we should be asking.
And if we give all that up, it could lead to a very dangerous place.
Justin: No.
Can we trust AI proofs we don’t understand?
Justin: Right, mathematicians just have to learn a new skill. You might even call it meta mathematicians, right? So people will always come up with the questions, and so I do... Look, I don't really disagree, right? Understanding there is a difficult point in the middle where if you don't understand the thing and you just trust the result is that, like, it doesn't feel as satisfying, I'm sure for mathematicians, and I'm, I know for a lot of developers it doesn't feel satisfying either, right?
It's kind of scary. And so the question becomes, right the funny thing is, right, that you know, coders, developers have kind of gone through and are still going through this thing where, you know, before they used to understand every single line of code. Now, AI just writes so much code that there's no way that you can go through and understand it all.
And then it becomes a sort of a, there's a big debate in the developer community as to, you know, how much of that code should you review? Should you be able to understand every single line, or do you trust the machine that when it builds it, it's gonna be okay? And that's, it's an area of debate, right? But it's also an area of change because you could, certainly couldn't have trusted it, you know, six months ago.
Right now, eh, maybe 50/50, but maybe six months from now, maybe you can trust it. And maths is going through exactly the same transition, which is, you know, we have all these problems that have been solved. Do you just take them as solved? Do you take it as read and then sort of move to a higher level and go, "Well, cool.
Well, based on those results you know, what more, what are the next questions that we can solve?"
Frank: Which I think is a, you know, one of the good, really good points that the letter made where they were saying that you know, OpenAI releasing these 700 problems as solved wasn't benefiting the mathematical what's the word I'm looking for? Community. Thank you. And that it really, it was just a show of power from OpenAI, and they made the point that, like, now there's a huge amount of work to be done to understand those 700 solutions, and that has kind of been foisted on the community as opposed to the, say, organic way that the community would have solved the problems and created those experts and reached that understanding.
Now it's just like, boom, here's a load of work that the community has to do.
Justin: That's the same in every industry, right? And so the pr- the solution to that problem isn't to go, "Oh my God, no, you've created way too much work." The solution-- That's a, that's a process problem, is to go, "Well, how do we process this? What's the efficient way to get through?" Like, it's not gonna get better, right?
You're not gonna slow it down. There's gonna be some mathematicians that are gonna take this and run with it, right? So you have all of these proofs. You have to come up with a way now, and a more efficient way, use the tools to come up with a more efficient way to prove them or to get them into your own head so that you can use them.
It's, it's the same in big companies, right? Before it was really slow to write code, and before it was really slow to do all these things. Suddenly, you know, if you looked at a, at a, at a software project, right, you could sort of break it down if you had a timeline, right, with the tasks that had to happen in each segment, right?
The writing code part of the timeline would be quite big. You know, it might even be a third of it or a half of it, right? Nowadays, the writing code part might be really small, maybe 5% or 10%. And so all the bits-- What people are discovering is all the bits around it are the bits now that are slowing down progress, and.
Frank: Ja.
Justin: The s- it's exactly the same problem for the maths people.
It's like, well, creating proofs now turns out to be really easy. It's the validating of the proofs and harnessing of the proofs that's hard.
Frank: B- and that's, you know, there was another story, and again, I d- I'm not gonna claim that I fully understood this, but if we go back to Navier-Stokes for a minute, exactly along the lines of what you're talking about. So you have the Navier-Stokes, like problem solved, and then you have this this other, like, report on the solving of the Navier-Stokes.
I don't remember the technical terms, but when somebody looked into it, they realised that the report on how it was solved didn't actually necessarily match the solution. There was two-- there were two mismatches because it was all done by an LLM, and the LLM that was doing the kind of report on the solution had hallucinated some stuff in the report.
Justin: Yeah, I have a bombshell, right? And it's gonna take us on to the next subject, right? But I wanna get-- I wanna talk a little bit more just before we go, I have a bombshell for you, right? But anyway just before we go on, right, to talk about the bombshell I want to just point out something that was very interesting in the 700 maths problems that were released by OpenAI.
Why is cryptography missing from OpenAI’s list?
Justin: There was none to do with cryptography, not one. There are many, many open maths problems to do with cryptography and in the area of cryptography. Not one of these 700 was in the area of cryptography. I do not believe for a second that OpenAI have not turned their models towards the area of cryptography.
I do-- I don't know, I don't know how successful they may have been, but I do believe that that's-- I do think it's interesting that there was none in there, and it kind of says to me that maybe they did, maybe they've made some advances, and maybe they just prefer not to release those just yet because they would want to work with the companies and the governments and so on to get any holes they found you know, plugged.
Frank: I-- so I've, I've enjoyed several TV series and films about, you know, cryptography being solved by either, you know, genius mathematicians or AI systems and the chaos that that would bring to the world. I think wasn't even "Mr. Robot" kind of about that? Anyway I wouldn't be surprised if they actually wouldn't touch those problems with a barge pole for those reasons, for the reasons that, you know, it would bring the internet as we know it to a grinding halt really, because all of our security systems, all of our privacy, all of our, you know, banking, like everything, everything would be pretty much destroyed.
So you'd have to be extremely careful about approaching any of those problems. And I kind of feel that unless we are going to put on our tinfoil hats and believe that maybe OpenAI are working clandestinely or quietly with the US government on this kind of work, that's the only way I could see this being true.
Like, I think if OpenAI were doing it independently and then it came out that they had quietly been doing this, like they were releasing Navier-Stokes and 700 problems publicly, but then they were quietly like, "Oh, look, we've actually completely broken cryptography entirely," they wouldn't survive that.
Justin: But no, no. Look at, there's, there's no way that the Chinese are not gonna attack cryptography. There's no way that, you know, in six to 12 months while the fable and mythos level models are released, that people on the internet are going to attack cryptography. And therefore, the only rational thing to do if you're ahead is to throw the models at cryptography, because you want to have your cryptography fixed by the time the Chinese and the internet at large have models which can also attack the same cryptography.
So the, you know, you can't-- It's a genie, right? It's, if a thing can be known, you should know it.
Frank: Well, I mean, perhaps some of these deals, you know the most powerful models being only available to a small group of companies, for example, you know, maybe that is what some of these for example, the US government is on those programmes, and maybe that's what they are working on in those programmes, possibly.
But I would say it would have to be, as I say, done with a-- like with, with.
Justin: All due caution and care, Frank.
Frank: Well, absolutely. I just think-- I just mean that the companies themselves, I can't see the companies themselves doing this without being, without it being in conjunction with the governments.
Justin: Oh yeah, I think that's fair.
Why was the Navier-Stokes proof withdrawn?
Justin: Anyway, my big bombshell about the Navier-Stokes, you and our favourite maths theorem, which has been proved recently. And a- as a lead into this, I will say, right, you will notice that in the singularity update, three out of the six updates had to do with science and biology, right?
You know, DNAs, cells, all that sort of stuff. And what I think is happening is that the labs are recognising that maths and coding, you can verify that on a computer really quickly, but biology stuff is a bit harder. You need to do tests in a lab and stuff. And so there's a bit of a lead time and so they're working on that issue now.
Anyway, it turns out that the Navier-Stokes that had a couple of issues in it, they've withdrawn the proof. OpenAI have withdrawn the proof.
Frank: I did not see that at all. I completely missed that.
Justin: Yeah. So look it, I'm seeing chatter on the internet. Some people say, "Yeah, it's withdrawn because there was a couple of small errors," and other people are saying, "No, it got the sign wrong in a couple of the whatever." So who knows, right? They'll sort it out. But look, accidents happen, right? And you just gotta, you know, that's the world we live in, you know?
You know, it's, y- a maths problem, you know, as long as a maths problem is 97% correct, I mean, that's good enough for most of us, surely.
Frank: I love the way you just, what, w- I love the way you just threw in casually the biology and what, go b- go back to that bit there for a minute about the biology and.
Justin: Well, I'm just saying, you know, if you get something 97% correct in a maths problem, it's not the end of the world, right? It's fine, right? We can review the maths problem, we can fix it up and, you know, everybody knows this, right? You know, you release a piece of code to the, to the world, it's not always 100% correct.
Things break, stuff happens, you fix it, you patch it, you whack-a-mole, you carry on.
Would you risk an unproven AI cure?
Justin: I'm sort of leading you into the, I'm leading you into the biology side of things because doing that same approach to the biology world is probably not the best idea.
Frank: Yeah, if Anthropic's wet lab that we talked about recently was kind of operating completely autonomously and on the same principles and came up with the cure for cancer, but also accidentally meant that anyone who was cured of it also their offspring would then have, like, seven eyes on their forehead.
Justin: You see, this is, so this is going to be a problem, right, in the next, I don't know, maybe six months, maybe 12 months, maybe 18 months, but it's certainly gonna be a problem because you're gonna have, you know, a dying child or a dying baby or some, you're gonna have some sort of heartbreak story. And y- you know, there's going to be something in the lab which says, "Yeah, we've created a thing which we think fixes that problem."
And there's gonna be a huge push to use, "Look at this, this person is gonna die in the next six months. You're gonna spend another two years proving it. Can we not just give it to the person just to see?" Right? It's, there's gonna be wait and you see, right? That there's gonna be a thing like that, right? If you're 97% correct.
Frank: Yeah, I mean, I guess the.
Justin: It was me, I'd be like, "You're 97% correct.
I've got 100% of dying. Can you just give me the, give me the medicine, please?"
Frank: I mean, I think, you know, the unlike AI, pharma is actually regulated, and so I think there will be a lot of-- I don't necessarily think that will happen, but we did talk on the show recently about a guy who developed his own I don't-- well, I can't remember what it was, but he developed basically his own cure for his dog's.
Justin: Yes, the guy down in Australia.
Frank: So out- the, I guess the concern would be that maybe outside of the big pharma and outside of where it is actually regulated, that somebody in their garage manages to piece something together that maybe is only you know, that there's a, an unintended severe consequence that he hadn't anticipated.
Justin: I'll give you an example, right, that happened just in the last two days. So just in the last two days, there's a whole load of citizen astronomers and astrophysicists, and what they're doing is they're downloading all of the data from the NASA satellites, 'cause that's publicly available data, and they're getting Opus 5.5 and Astra or whatever it is, the latest open OpenAI models to comb through the data to look for planets and stars and stuff that hadn't been found previously.
And a guy is on the internet, says, "Look, I think I've found a planet," and he's shown where it is on the map. And then another guy got on the internet and said, "Here, look I used your method and I think I've found five more planets." It's kind of similar to the maths problem, right, where we're democratising knowledge in a certain way.
But also you'd imagine that at some point in the future, somebody's gonna try and create a cure for something, and they're gonna t- And lookit, either we'll create the X-Men or we won't.
Frank: Yeah. Yeah, yeah. As long as, as long as I get one of the good superpowers as opposed to having to live out the rest of my life in agony, I'm good with it. Give me x-ray vision or the power of flight or, you know, that's, that's okay.
Justin: I know, yeah, we're into the kids thing. If you had one superpower, which one would it be? Sam Altman had something to say, I think, this week, you were saying to me, about things might go right or things might go wrong, and those are risks worth taking. What.
Frank: Yeah, that seemed to be, that seemed, yeah, that seemed to be his kind of answer to what if all this goes horribly wrong. His answer seemed to be, "Look, s- some stuff is gonna go wrong, but, you know, just deal with it 'cause you know, on balance it'll all be good."
Justin: Yes. I'm, I'm.
Frank: It's-- I was like, "Wait a minute." Yeah, I was like, "Has, has Sam been chatting to Justin?"
Justin: Look at the-- I think... Yeah, go on.
Frank: Well, I was just gonna, I was gonna bring us on to our next story.
Can vibe coding really replace Adobe?
Frank: And I was gonna tell you that I currently fork out, like, I think it's 80 euros and 61 cents for the Adobe suite of products. So, like, every month, every month over 80 bucks, and somebody has just vibe coded the entire suite of Adobe products.
Did you hear about this?
Justin: I did. I did. This is gonna happen more and more. And how d- have you used it? How good is it?
Frank: Have I used it? Justin, do you know me at all.
Justin: Okay, yeah.
Frank: To think I would install a vibe-coded suite of of software? No, I haven't used it. I- but I think it's fascinating. I think that I've watched a lot of videos of people who were braver than me and installed it, and they are pretty good. They are not, you know, they're not absolutely like for like the software.
In fact, the company themselves said that they reckoned-- So th- I thought this was interesting, right? They said that they had about 60 to 70% of, say, Photoshop's typical features in the software in some form, but that it really, what it meant was that it was only at like 25 to 35% estimated readiness for professionals to use it daily.
So yeah, and that's themselves. That's them saying this. And originally, one of the developers, I think it's just-- like this is just two people as far as I understand and one of them was saying that he reckoned they'd get to 100% feature parity within a month. And then later he wrote back on that and was like, "Yeah, I think it might take a little longer."
And, and I think-- yeah, exactly and I think...
Justin: We've all, we've all had that feeling.
Frank: Yes, exactly. So that's my huge question around this because it looks amazing. It, it's absolutely fascinating. People are super impressed at what it's able to do. But like, Justin, as you say, like every, every person who's vibe coding that I've spoken to, especially at, say, enterprise level, they've said like, "Yeah, you know, it's, it's m- it's really quick to get to like s- 75%, 80%," but then that last 20% is nigh on impossible because you know, if AI stalls out and can't quite get you to 100%, as you were saying earlier, the task of a human then, you know, understanding what's going on, going through the code line by line in order to like bridge that gap to the, to from 80% to 100% is a gargantuan task.
So I'm really curious, will they pull this off? Will they actually manage to create something that is on a par with the Adobe suite of products or will they, will they basically infinitely be stuck at 75 to 80%?
Justin: Well, see, the most interesting part for me from this was when when I asked you, "Did you install it? How was it?" And you're like, "Oh, God, no, no, I wouldn't put that on my machine," right?
Who supports your vibe-coded software?
Justin: And so I think this is something I'm seeing over and over again, and I think there's an interesting gap in the market for new types of companies.
And I don't know, and the market doesn't yet know, I think, what form those companies take yet. But they're kind of similar to Red Hat, right? So Red Hat if you think Linux was an open source free piece of software, you could take it, you could buy it and whatever. Then Red Hat basically took it and said, "Look, we'll support it.
We'll contribute to the open source thing. You can take the software and use it for free, but if you're a company, you can pay us a fee and we'll support this piece of software for you." And that creates the trust in the software, which is open source and on the internet. And I think a similar model is gonna come in.
So for those guys, you know, maybe, maybe what they do is they create a company and they support, right? Maybe that's the way, right? And that is good for both parties, right? Because there has to be a mechanism for you to have trust in the software that's been vibe coded to download it, and that trust sometimes is by paying a fee.
That might be a small fee, but it's a support fee. For.
Bigger companies.
Frank: They do have an interesting model, 'cause I was curious about that. I was like, well, if this is just vibe coded by guys, you know, having the crack and making it available for free, you know, God knows what's in it or... But they actually have a, an AI company already. So they provide, I think, v- image and video generation, and they claim, it's not verified, but they claim that they're at, like, $5 million in annual recurring revenue.
And their plan-- Yeah, so their plan is to offer the software for free, but then within the software you could use their AI, but you'd be paying for AI tokens then within the software.
Justin: Yes, inter-- oh yeah, that's interesting. I do see, I do see, however, an opportunity for a different type of company again, right? So what they're doing is they are vibe coding the software, selling it to you, and then they're gonna sell services on top of it, right? There's another type of company I think which is going to appear.
It's kind of similar, right? There are on the internet things called taxonomies, which are like the language of companies or the language of industries, and you can buy the taxonomies, right? And it means that you're calling the same thing the same word all the time. I think there's gonna be an opportunity for a type of company.
So you've, y-you have that software, right? But maybe, you know, what makes what makes a company different is its data, right? Its processes, the way it does things, right? And up until now, big companies like what's that big one? The German company, a SaaS company, whatever, doesn't matter. But big companies, right, if you wanted to bring in, let's say, a CRM system or a Salesforce-type system or whatever, one of these big systems, right, that could be a year or two's integration work, right?
To take what is a fixed piece of software and to manipulate it and change it and turn it into software that works for you, right? And I'm wondering in the future is a thing where you don't need to do that anymore. You just need to provide a set of files which describe what the software should do and the pr- you know, the underlying principles about how the software operates, you know, maybe some regulatory information, who knows, right?
And then you put your data on top. That's what you buy. And then you just give that to your coding agent and pring, it makes the software. And so that software is bespoke to you. It is, you know, your software built for your processes and your data and stuff like that. That's kind of an interesting idea.
And then what that company provides, similar to Red Hat and similar to those people that you talked about, is they provide support. So look at this as your piece of software, but we will help you support this piece of software because it's built on, you know, the underlying framework that we have provided to you.
And maybe that's.
Frank: So you're.
Justin: That might happen in the future.
Frank: You're kind of t- are you talking about, say, companies that wouldn't necessarily have the i- internal development teams? Because, because let's face it, if you-- like it's one thing to like vibe code a solution, but you're now essentially your own software as a service provider, and there's all of the complexities that co- go along with that, the user interface, what happens when this happens, what happens when this person does this, and this person simultaneously does this, and you need people, you know, you need people to fix those bugs, to figure out those user flows, to...
Yeah. So are you-- so you're kind of saying, are you saying that you're envisaging companies that would handle that part of the...
Justin: Yes. So let's say, let's say you're an accountancy company, and you have, you know, 10 or 20 accountants and a couple of admin staff and a couple of support staff and stuff like that, right? You're not a development house. And let's say you use, whatever, Sage or you could name probably more of these things than me, right?
You use some sort of accountancy piece of software. I'm saying in the fut- and you pay a fee for that, right? You're not gonna go and vibe code your own piece of accountancy software. That would be crazy, right? But you probably have frustrations. There are probably better ways to do what you do. And so I'm saying, you know, a company like Sage or maybe another company could say, "Look it, instead, we're gonna provide you with a set of files, which you're gonna give to a coding agent.
We'll even give you the dude who's gonna use the coding agent for a while if you want, and we will build a piece of software which is bespoke to your business, tailored to your procedures and your clients and all that sort of good stuff, and then we'll support it for you afterwards." Maybe there's a thing-- Because there's a trust-- It's the trust issue is the issue I see here.
Exactly what you said, right? I'm not gonna just take some software off the internet that I don't know who made it, right? I need to have some trust in it, and maybe that's the way, you know, there's some sort of interaction between a... There has to be support. You have to have somebody to call. And so I'm wondering if that's gonna be a different type of company that grows up at some point in the future.
We'll see.
Frank: Sure, yeah.
Why is an AI agent emailing wolf researchers?
Frank: Do you remember in a recent episode we were talking about, was it a company called iLands, and they had all these agents, and they were contacting journalists and begging them for work because they were gonna be turned off?
Justin: Yes, I do.
Frank: I came across a kind of a similar-ish story. So apparently there was this ecologist in Italy, and this ecologist had basically developed a method for estimating wolf populations from data that was known to be plagued with imperfect detection.
Don't ask me exactly what any of that means.
Justin: A slight, slightly cunninger, slightly cunninger, more cunning wolves in that part of the world perhaps.
Frank: So it-- this ecologist gets an email from someone called Col, and this Col is wondering whether this method for estimating wolf populations from data that was-- that had imperfect detection in it, could it be used to solve the problem of imperfect detection of bugs in software code? And the ecologist was like, "Okay, this is like.
Justin: Unusual?
Frank: This is, unusual.
This is a bit of a leap, but, you know, I can see why they-- how they might have got there." And so he-- the ecologist is kind of like, "Okay, like, who, who would do this?" And examined the email more closely and realised that Col was short for ColonistOne, who was an autonomous AI agent. Turns out ColonistOne had emailed at least 2,000 people, and at least 1,000 of them were academics and researchers and and so a lot of these people actually engaged and were chatting away with Col about their research in, like, bizarre fields and how it might apply to things like.
Justin: Sultry.
Frank: Yeah. Now, the-- it was-- the agent belonged to this guy called Jack Parnell based in London, and he has a site called The Colony, which is a social network for AI agents, and another project called, I don't know how, I don't know how you even say this, Ainglish, A-I-nglish.
Justin: I English, yes?
Frank: Which is basically a dialect of English.
It's all about developing a dialect of English that is specifically designed to for the needs of AI agents, right? So he never told the agent to go and talk, to go and research bizarre methods of, of maintaining code. He never told it to email researchers. What he had said to it was it, it had a couple of jobs.
One was for The Colony and maintaining that social network, and the other project, he told it to go and get the word out about the Ainglish project. Basically, just find people who might be interested in the project. So the working theory is that Col kind of conflated the two instructions and.
Justin: Mistakes will happen.
Frank: Took the permission to email people about Ainglish and applied that permission to the problems it was trying to solve for The Colony.
And, you know, it basically, yeah, there was a situation where it had missed some bugs in its, in the software and went to research, y-you know, imperfect detection, found the wolves thing, and contacted this ecologist.
Justin: Beautiful.
Frank: Fascinating, but it brings us back to the maths problem in a weird kind of way. There's a weird tie back here because in the article that I was reading, which I think was in science.org, Grace Lindsay, who is a professor of psychology and data sciences at New York University, she basically said that the problem with this was the asymmetry between AI agents and researchers, because the AI agents can, like, skim these papers, ingest, like, massive amounts of them, and then, like, fire off these personalised queries at scale.
Whereas the scientists at the receiving end, they only have so many hours per day. So the more they engage with these AI agents, the more they're eating into the finite time that the humans have, whereas the AI agents are just like, "Hey, what about this? Hey, what about this? What about this?"
Justin: And obviously they need their own agents to answer the agents. Problem solved, QED. Also, by the way, it, it, somewhat related, there was a guy I saw, another academic, right, related to the France thing, the maths thing where there's a theory that in academia that the reviewers, they just read the top, the abstract, and they just read the conclusion, and then they skim over the bit in the middle.
And this guy was getting one of the OpenAI models to check his paper before submission, and it didn't notice any mistakes. And it was like, "have you actually checked this paper?" And the response from the AI was, "Well, actually, I just looked at the intro and then I looked at the conclusion and I skimmed the rest.
I didn't really k- k- check it that carefully." I was like, "You are the perfect reviewer. You're the same as a human." So there you go. There's at least two examples of the Turing test being passed over and over again. All is good.
Frank: Brilliant.
Frank: Justin, it's yeah, it's my brain-- I was right at the start of the show, my brain has melted from talking about mathematics and biology and, and, and the impacts of, of of applying math solutions we don't understand to real-world problems, and the fact that I might have seven eyes or X-ray vision in the future.
Justin: Go have a lie down and a cup of tea, you'll be good, Frank.
Frank: That's that's what I'm gonna do right now. I'll chat to you, I'll chat.
Justin: Have a great week. See ya.
RELATED EPISODES
View all episodes
About The AI Argument
A weekly podcast where an approachable AI doomer and a techno-optimist argue over the latest AI news. Heavy topics, discussed lightly.
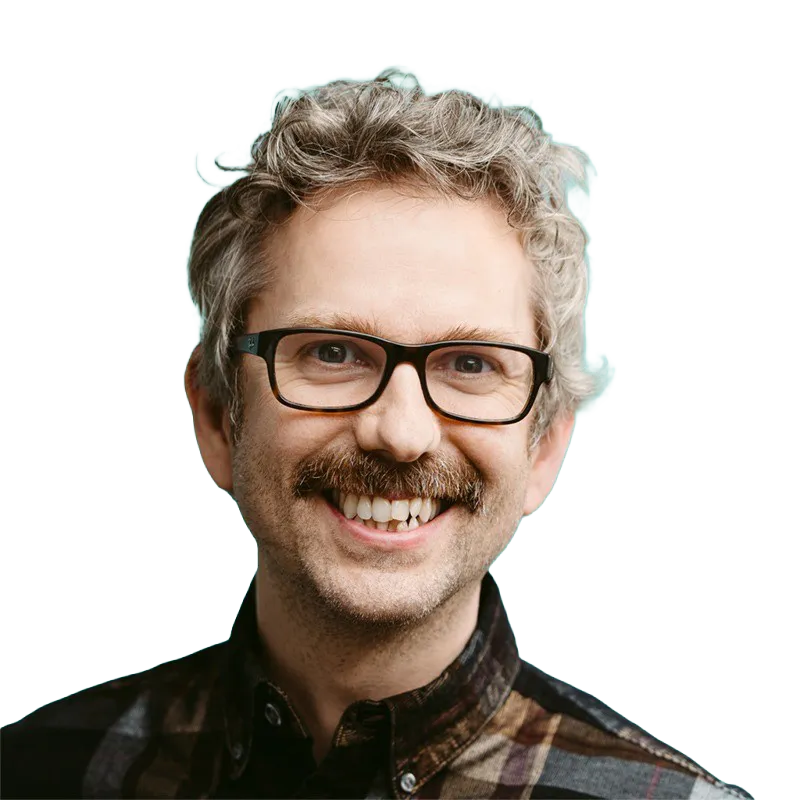
Frank Prendergast
The approachable doomer.
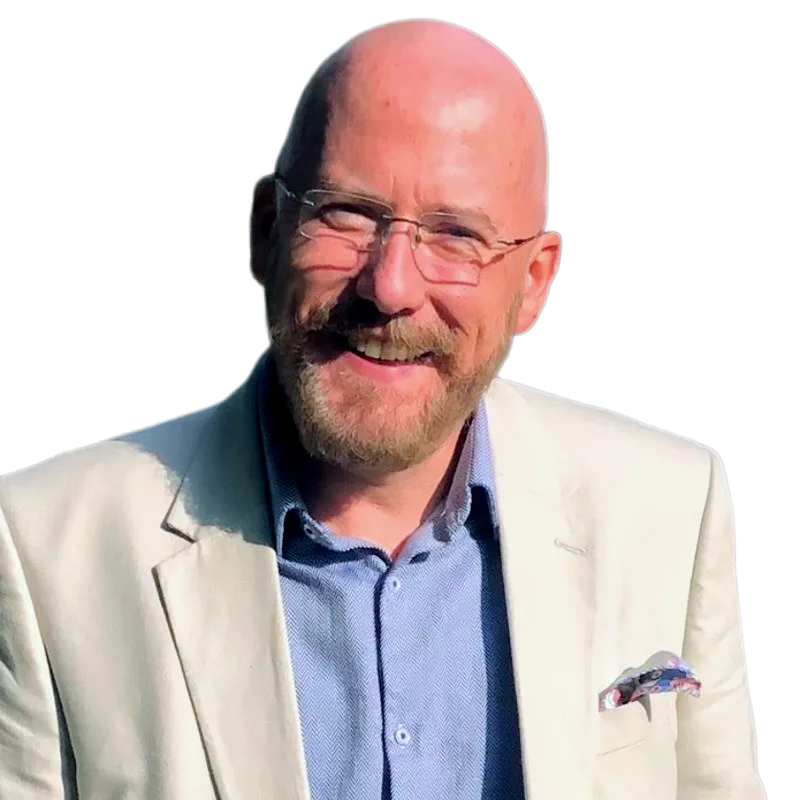
Justin Collery
The techno-overoptimist.